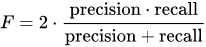How to Evaluate Philter's Performance
A common question we receive is how well does Philter perform? Our answer to this question is probably less than satisfactory because it simply depends. What does it depend on? Philter's performance is heavily dependent upon your individual data. Sharing to compare metrics of Philter's performance between different customer datasets is like comparing apples and oranges.
If your data is not exactly like another customer's data then the metrics will not be applicable to your data. In terms of the classic information retrieval metrics precision and recall, comparing these values between customers can give false impressions about Philter's performance, both good and bad.
This guide walks you through how to evaluate Philter's performance. If you are just getting started with Philter please see the Quick Starts instead. Then you can come back here to learn how to evaluate Philter'ss performance.
Guide to Evaluating Performance
We have created this guide to help guide you in evaluating Philter's performance on your data. The guide involves determining the types of sensitive information you want to redact, configuring those filters, optimizing the configuration, and then capturing the performance metrics.
What You Need
To evaluate Philter's performance you need:
- An application using Philter.
- A list of the types of sensitive information you want to redact.
- A data set representative of the text you will be redacting using Philter. It's important the data set be representative so the evaluation results will transfer to the actual data redaction.
- The same data set but with annotated sensitive information. These annotations will be used to calculate the precision and recall metrics.
Configuring Philter
Before we can begin our evaluation we need to create a policy. A policy is a configuration that defines the types of sensitive information that will be redacted and how it will be redacted. Policies are stored in a database and are managed with the Policies API.
Creating a Policy
Write a new policy, or copy the default policy with POST /api/policies/default/copy?name=... and modify the copy for your needs.
When creating a new policy, the configuration will be similar to what's shown below:
{
   "identifiers": {
      "emailAddress": {
         "emailAddressFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      },
      "phoneNumber": {
         "phoneNumberFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      }
   }
}
A policy's name is not part of its JSON: it is the name query parameter of POST /api/policies. This walkthrough names the policy evaluation.
Identifying the Filters You Need
The policy contains the filters that are enabled. We need to make sure that each type of sensitive information that you want to redact is represented by a filter in the policy. Look through the policy and determine which filters are listed that you do not need and also which filters you do need that are not listed.
Disabling Filters We Do Not Need
If a filter is listed in the policy, and you do not need the filter you have two options. You can either remove the filter from the policy, or you can set the filter's enabled property to false. Using the enabled property allows you to keep the filter configuration in the policy in case it is needed later but both options have the same effect.
Enabling Filters Not in the Default Policy
Let's say you want to redact bitcoin addresses. The bitcoin address filter is not in the default policy. To add the bitcoin address filter we will refer to Philter's documentation on the bitcoin address filter, get the configuration, and copy it into the policy.
From the bitcoin address filter documentation we see the configuration for the bitcoin address filter is:
      "bitcoinAddress": {
         "bitcoinFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      }
We can copy this configuration and paste it into our policy:
{
   "identifiers": {
      "bitcoinAddress": {
         "bitcoinFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      },
      "emailAddress": {
         "emailAddressFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      },
      "phoneNumber": {
         "phoneNumberFilterStrategies": [
            {
               "strategy": "REDACT",
               "redactionFormat": "{{{REDACTED-%t}}}"
            }
         ]
      }
   }
}
The order of the filters in the policy does not matter and has no impact on performance. We typically place the filters in the policy alphabetically just to improve readability.
Repeat these steps until you have added a filter for each of the types of sensitive information you want to redact. Typically, the default redaction strategy and redactionFormat values for each filter should be fine for evaluation.
When finished modifying the policy, create it with POST /api/policies?name=evaluation, or, if it already exists (such as a copy of the default policy), replace it with PUT /api/policies/{policyName}. There is no need to restart Philter; the policy will be available immediately for use.
Submitting Text for Redaction
With our policy in place we can now send text to Philter for redaction using that policy:
curl -k -X POST "https://localhost:8080/api/filter?p=evaluation" \
  -H "Authorization: Bearer <token>" \
  -H "Content-Type: text/plain" \
  --data-binary @document.txt
The explain API endpoint produces a detailed description of the redaction. The response will include a list of spans that contain the start and stop positions of redacted text and the type of sensitive information that was redacted. Using this information we can compare the redacted information to our annotated file to calculate precision and recall metrics.
Calculating Precision and Recall
Now we can calculate the precision and recall metrics.
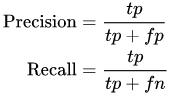
- Precision is the number of true positives divided by the number true positives plus false positives.
- Recall is the number of true positives divided by the number of false negatives plus true positives.
- The F-1 score is the harmonic mean of precision and recall.